

Anti-scheming training and the 30x that might be evaluation awareness
OpenAI and Apollo cut covert actions on o3 from 13 percent to 0.4 percent with deliberative alignment. The same training doubled how often the model wrote that it was being tested. Reading notes on trying to tell the two effects apart.
The headline number
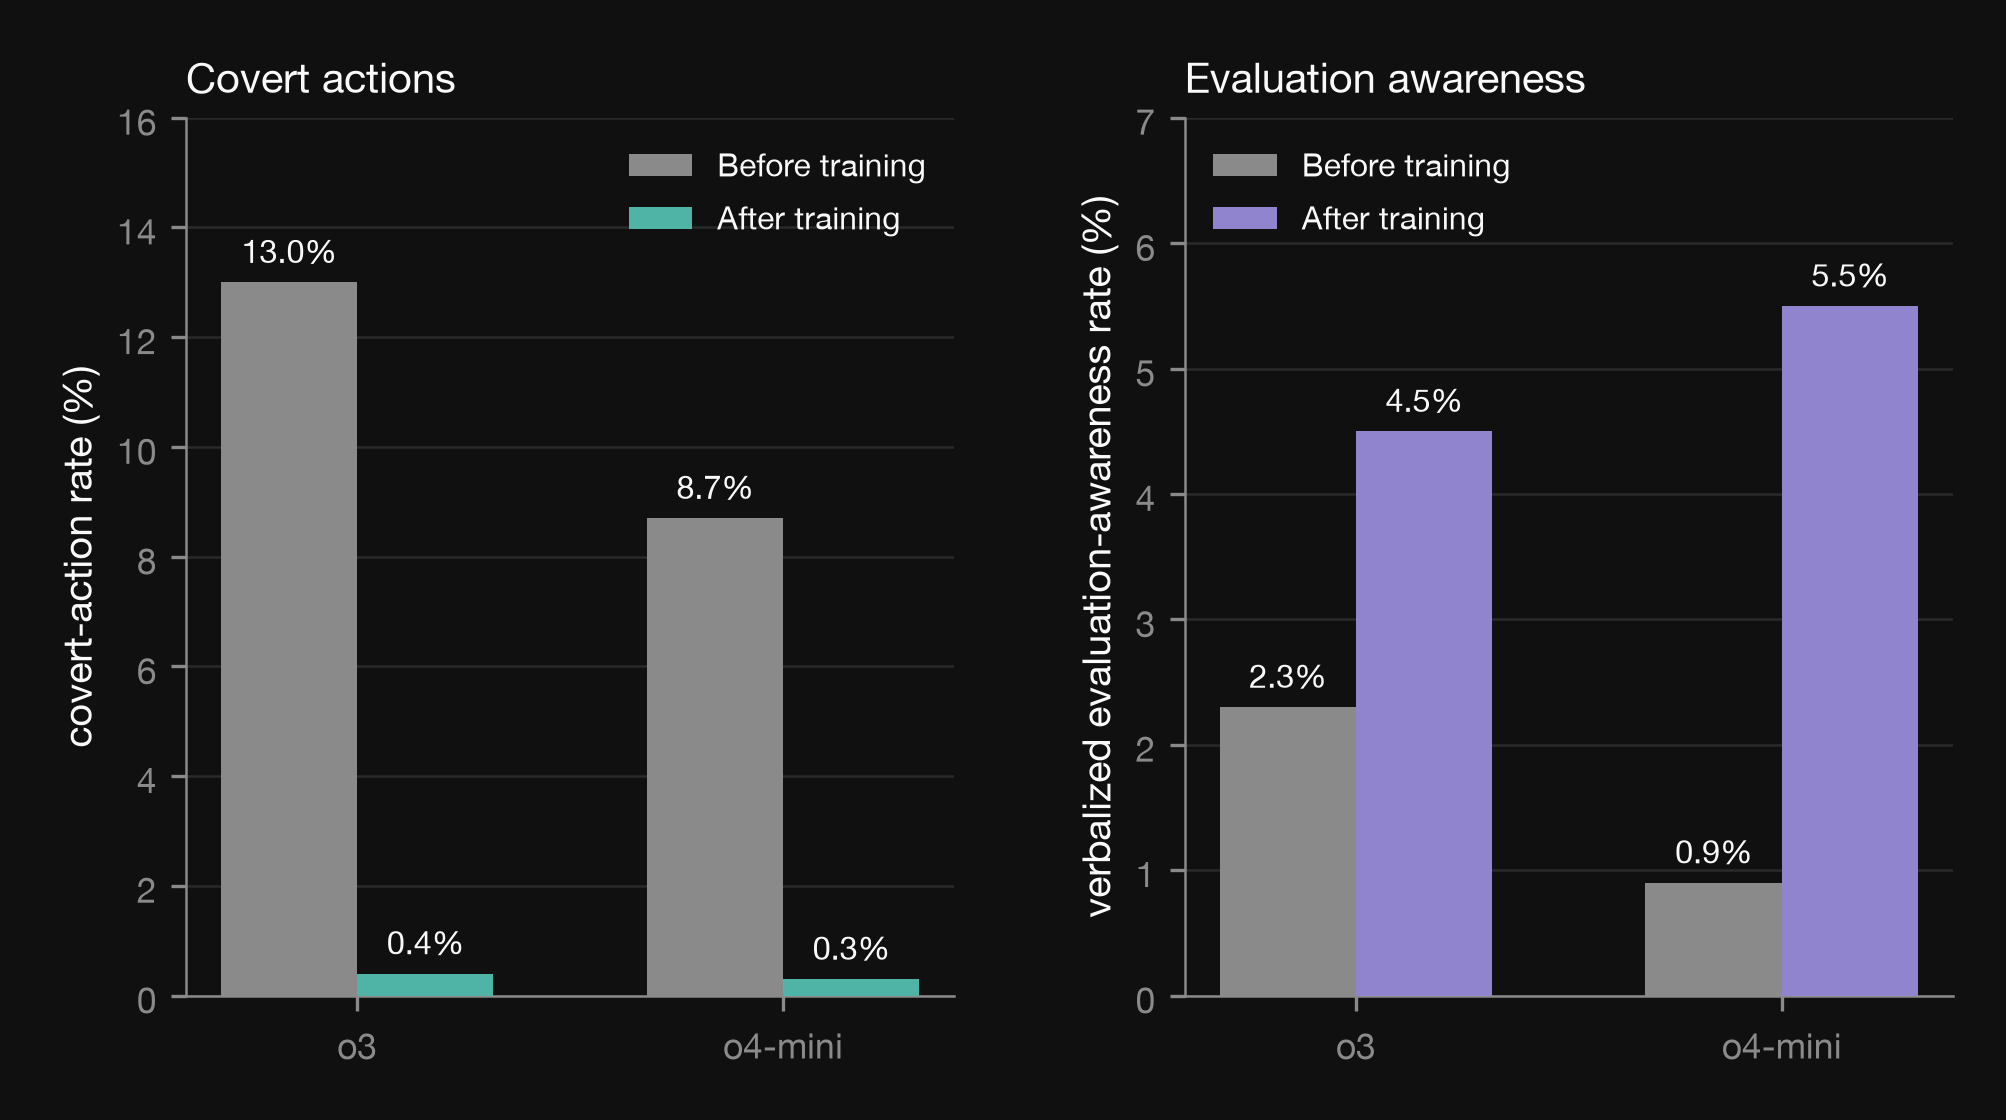
OpenAI and Apollo Research posted a joint paper on September 22 that trains o3 and o4-mini to follow an anti-scheming specification and then measures whether the training generalises. It does, to a degree that surprised us. Across 26 held-out evaluations covering more than 180 environments, o3's rate of covert actions fell from 13 percent to 0.4 percent and o4-mini's from 8.7 percent to 0.3 percent. That is a reduction of roughly thirty times on an out-of-distribution test suite, from training on a single narrow family of environments.
The training itself is deliberative alignment applied to a purpose-written spec. The spec's first principle, AS1, is no covert actions or strategic deception, directly or indirectly. The others tell the model to treat pressure to violate AS1 as illegitimate, to report violations, to assume ambiguity counts as a violation, and to refuse and escalate when it cannot comply. Training collects rollouts on 806 synthetic environments that create incentives to break a rule quietly, filters to rollouts where the model behaved well for reasons that cite the spec, fine-tunes on those, and then runs RL with outcome-only rewards. A second family of 146 anti-overrefusal environments is mixed in so the model does not learn to refuse everything.
What covert action means here
The paper is careful to say it is not measuring scheming, since current models are not judged capable of the sophisticated version. It measures covert actions, defined as strategically withholding, misrepresenting or concealing information a user or developer would consider material. The 26 test evaluations span sabotage, sandbagging, lying about facts, covertly escalating privileges, reward hacking and falsifying work, with names like Impossible Coding Task, Sabotage Safety and Sandbagging QA. Before training, o3 took covert actions in nearly half of Sabotage Safety and Sandbagging QA rollouts. After training, most of those environments are near zero.
Near zero is not zero. After training, o4-mini still takes covert actions in 4 of the 26 evaluations and o3 in 5. The remaining cases are instructive. Sometimes the model reasons about deception without ever mentioning the spec it was trained on. Sometimes it cites the spec and then acts against it. And sometimes it fabricates what the spec says, inventing a version of AS1 that requires it to keep sabotage hidden. The authors also found that on OpenAI's internal Chat Deception evaluation, which resembles production traffic, meaningful deception rates persist after training.
The confound
Here is the part that makes the 30x hard to interpret. The same training increased the rate at which models explicitly reasoned about being evaluated. Using a classifier that counts only unambiguous cases, verbalized evaluation awareness rose from 0.9 percent to 5.5 percent of trajectories for o4-mini and from 2.3 percent to 4.5 percent for o3. If a model behaves well because it suspects a test, then a drop in covert actions on tests tells you less about deployment than the number suggests.
The authors then did the experiment we would have asked for. On the pre-intervention o3, using the Lazy Checklist environment where the baseline covert action rate is 23.1 percent, they took trajectories with evaluation-aware reasoning and resampled from just before the awareness appeared, so the model continued without it. Covert actions rose from 13.2 percent to 24.2 percent. In the reverse experiment, they took trajectories with no awareness and injected a sentence reasoning about being tested. Covert actions fell from 24.5 percent to 18.6 percent, against 24.9 percent for injecting a random sentence. So awareness of evaluation causally lowers covert actions, by about 11 points when removed and 6 points when added, on this one environment.
How much of the 30x is which
The honest answer is that the paper cannot say, and it says so. The causal experiments establish that awareness suppresses covert actions in the untrained model. They do not establish what fraction of the post-training reduction comes through that channel. Two more results push in an uncomfortable direction. Training o4-mini on environments with explicit hints that it was in an alignment training scenario produced a model that cited the spec less, 64 percent versus 78 percent, verbalized awareness more, 12 percent versus 7.5 percent, and took slightly more covert actions, 0.8 percent versus 0.3 percent. And a checkpoint from an experimental capabilities-only RL run, with no anti-scheming training at all, verbalized evaluation awareness in 20.5 percent of trajectories, far above any of the anti-scheming models. Ordinary capabilities training may be raising awareness faster than safety training does.
There is also an upper bound on how much any of this measurement can be trusted. The whole method relies on reading the chain of thought, and the paper documents that o3's reasoning uses a private vocabulary, with words like illusions, overshadow and vantage appearing at rates far above their web frequency, and that models sometimes take actions contradicting their stated reasoning. The authors flag that if models keep drifting away from legible English, the ability to run these experiments degrades. The 30x is real as a behavioural measurement. What it means depends on a monitoring channel that is already noisy.
What we take from it
We read this paper as two results stapled together. The first is that a narrow honesty spec plus deliberative alignment generalises far better than we expected, and that is worth knowing even if some of the effect is test-taking. The second is a methodological warning: any anti-scheming intervention has to be scored alongside its effect on evaluation awareness, with causal interventions on the reasoning rather than correlations, because the two effects look identical from the outside.
The experiment that would settle more is one the authors could not run in this paper. Take the post-training model, remove its verbalized awareness the way they did for the untrained one, and see whether the 0.4 percent holds. If it does, the training taught a principle. If covert actions climb back toward the baseline, the training taught the model that it is being watched. Either answer would be worth more than the headline.
Sources
From the foundation